

Every company in the world can now get its hands on a powerful AI model. That, says Amritanshu Jain, is no longer the hard part. The hard part is running it — at the right speed, at the right cost, without it falling over when demand spikes. “Nobody actually needs the fastest or the cheapest inference,” the Simplismart co-founder and CEO says. “Companies need speeds and costs that make sense for their own applications.”
That gap between a model and a working product is exactly where his Bengaluru startup lives. Simplismart builds the software that sits between AI models and the GPU infrastructure they run on, tuning how each workload is deployed so it hits its own targets for latency, throughput and cost. Founded in 2022 by Jain, a former Oracle engineer, and Devansh Ghatak, a former Google engineer, the pair met at BITS Pilani and have spent four years building what Jain calls “the software between the model and the GPU”.
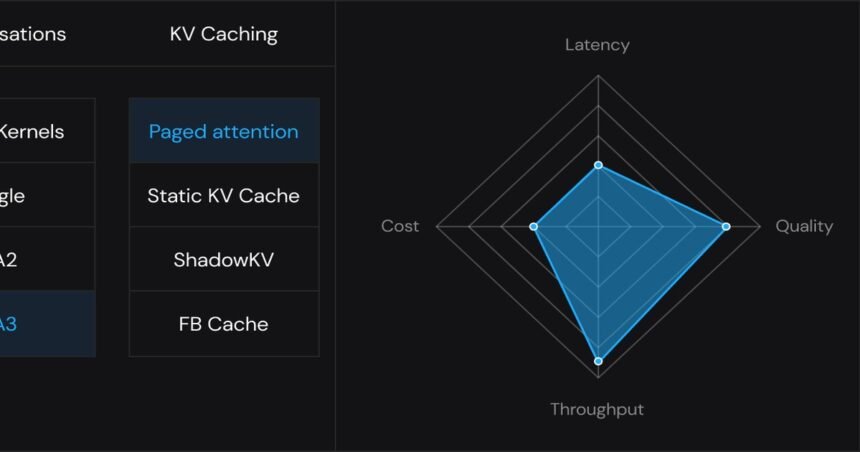
The problem Simplismart solves is one every AI company runs into the moment it goes from demo to production. Running a model is not just a matter of picking a GPU. The company says decisions around inference frameworks, quantisation, caching, tensor parallelism and custom CUDA kernels directly decide how quickly an application responds and what each interaction costs — and the right answer changes with every workload. A real-time voice agent needs sub-100-millisecond responses; a document-processing pipeline wants maximum throughput at the lowest cost. Simplismart automates those choices, searching across configurations and serving each workload with the setup that fits it best.
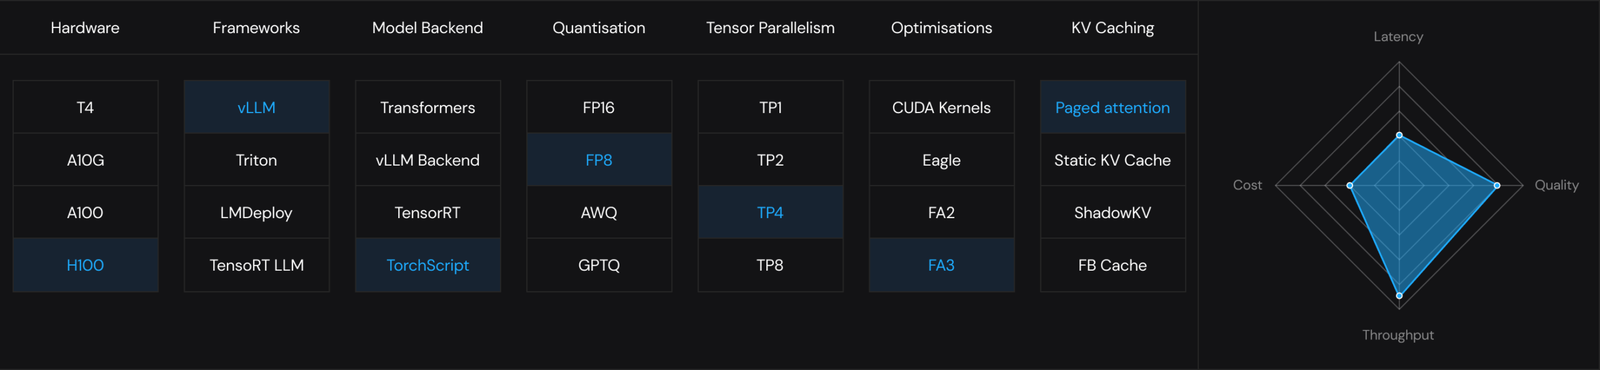
The platform covers more than 150 open-source models, or customers can import their own weights, and it deploys either in Simplismart’s cloud or inside the customer’s own private cloud or on-premises setup — an option the company says matters most in regulated sectors such as banking and financial services. One control plane manages deployments across clouds, auto-scaling kicks in within 500 milliseconds for spiky traffic, and the company reports 99.99% uptime for production deployments. It also offers fine-tuning tools, automatic scaling as demand shifts, and performance monitoring, while cloud providers can use the same software to build their own managed inference services on top of their GPU fleets.
The customer list shows how wide that net has spread. Video-generation platforms HeyGen, Higgsfield and InVideo, enterprise AI startup Ema, logistics platform Shiprocket and jobs platform Apna all run production workloads on Simplismart across video, voice, multimodal and enterprise AI. The company says InVideo cut its GPU serving costs by 56% on the platform, and communications platform Exotel reported cost-per-minute reductions of up to 57%. For Ema, the company says its optimisation search turned a target of roughly 200 milliseconds at about 9 cents per million tokens into a production configuration running at 7 cents and 180 milliseconds. Indian cloud provider Yotta uses Simplismart’s technology to power the serverless inference layer of its Shakti Studio platform.
That traction has turned into serious momentum. Simplismart says its annualised revenue run rate has grown 14-fold over the past six months, with more than half of its revenue now coming from the United States even though it has more customers in India. The 58-person team previously raised $7 million in a Series A round led by Accel in October 2024, and has now closed a $14 million Series B led by Dallas Venture Capital, with Nvidia, Accel, Shastra VC and Micromax participating — a round TechCrunch reported values the company at about $100 million. Nvidia is also working with Simplismart on technical integrations, including around its Dynamo inference software, and has helped introduce the startup to potential customers and partners.
More Read
The new capital will go towards developing the inference platform further — including a dynamic GPU scheduling layer to match AI workloads with available computing capacity across regions and time zones — expanding partnerships with cloud providers and sovereign AI players, and growing its presence in North America and other global markets. As AI shifts from a race to build the biggest model to a race to run models economically at scale, Simplismart’s bet is that the winners will be decided not by who has the most GPUs, but by who squeezes the most out of the ones they already have.
Keep reading: Seven Minutes From Sky to Doorstep: Inside Skye Air Mobility, India’s Drone Delivery Pioneer · The Shop That Fits in a Chat: Inside Robnu, the Surat Startup Running India’s Marketplace Sellers from WhatsApp · More Industrial Automation & Technology stories
Like stories like this? Add Exceptional Technology as a preferred source on Google to see more of our reporting in your search results and Discover feed.